Claude AI production deployment requires more than connecting an application to a language model. Enterprises need reliable architecture for handling requests, coordinating workflows, protecting sensitive data, evaluating outputs, and managing operating costs.
This guide explains Claude AI architecture. That means the system built around Claude, rather than the model's internal design. It covers layered application architecture, agent orchestration, security controls, observability, and practical approaches to production cost management.
The goal is to help engineering teams design Claude-powered applications that remain reliable as workloads, integrations, and operational requirements grow.
What Is Claude AI Architecture for Production Systems?
Claude AI architecture for production, also called Claude production architecture, is the system design used to operate Claude-powered applications reliably in real-world environments. It typically separates application logic, workflow orchestration, and model interactions while applying security, monitoring, evaluation, and cost controls across those components. The architecture must also support error handling, controlled integrations, and human oversight where necessary.
AI in 2026: Production Is the Only Benchmark
Production readiness today is a much broader demand. It's no longer just speed and availability. You now need reliable autonomous decisions, solid defenses against prompt injection, predictable costs, and comprehensive audit trails. Your systems must also degrade gracefully when challenged. Many teams reach this point after a pilot, and this guide on moving AI pilots into production covers that step.
New Enterprise Requirements
The requirements have escalated. You are building agentic systems that manage workflows independently. This involves multi-agent collaboration for complex tasks. Handling vast contexts, like entire codebases, is routine. Observability must now evaluate decision quality, not just technical performance.
Why Prototypes Fail at Scale
Common development habits will undermine you. Hardcoded prompts fail against production's variability. Inadequate error handling causes silent failures, eroding trust. Unmonitored token usage leads to cost overruns. Security gaps invite prompt injection, and a lack of fallbacks creates single points of failure. Product and retention planning sits outside this guide, and Claude AI app development from MVP to production and scale covers it.
Building an AI Factory
Operationalizing Claude requires repeatable production discipline. Standardize prompt versioning, model routing rules, and effort policies across teams. Automate regression testing against refusal rates, token usage, and behavior at each effort level before release. Treat Haiku, Sonnet, and Opus as managed production assets, with controlled rollouts and measurable performance baselines.
The Pressure and the Prize
Market tolerance has vanished. Scrutiny on AI ROI is intense, and compliance is mandatory. A clear AI strategy ties each use case to a measurable outcome, and AI strategy consulting services can help set it. Organizations that build reliable systems early can earn stakeholder trust sooner. Success depends not on the model alone, but on the production-grade system you wrap around it.
Designing Scalable Claude AI Architectures
Claude offers a model family, extended context capacity, and controllable reasoning depth, introducing structural decisions that directly influence latency, traceability, and cost predictability at scale. A sound Claude API architecture treats each of these as a design decision.
Layered Architecture Pattern
Structure your system in three clear layers. The Application Layer enforces business rules and validation. The Orchestration Layer routes requests across Haiku, Sonnet, and Opus using task-aware logic. The AI Layer manages Claude-specific controls such as version pinning, effort settings, and token accounting. This separation limits blast radius during upgrades and enables controlled experimentation.
Teams that build this stack often work with generative AI software development specialists.
Core Layers of a Production Claude Architecture
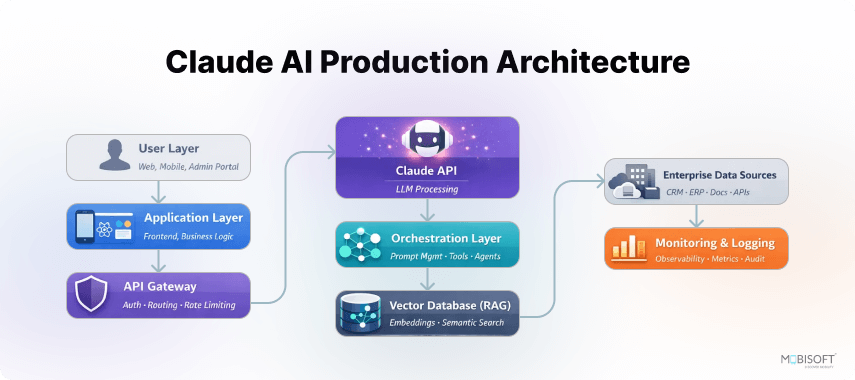
The three layers above sit inside a wider structure. Security and observability apply across all of them.
| Layer | Responsibility | Example Controls |
| Application | Business rules, user interaction, validation | Permissions, approvals, business logic |
| Orchestration | Workflow coordination and tool execution | Routing, retries, fallbacks |
| Model integration | Claude API calls and prompt management | Model versioning, prompt versions, token limits |
| Security | Protect data and restrict actions | Least privilege, sandboxing, access controls |
| Observability | Evaluate quality, reliability, and cost | Logs, evaluations, latency and usage metrics |
How the diagram reads. A user request enters the application. The application passes validated requests to the orchestration layer. Orchestration calls the Claude API and, where approved, connects to tools and data sources. Security, monitoring, evaluation, and cost controls apply across every one of these components.
Building Production-Ready AI Agents?
Explore how custom AI agents and secure orchestration can support enterprise workflows.
Agentic Architecture Considerations
Claude’s large context window supports multi-agent workflows, but AI agent orchestration needs explicit coordination between agents. Decide whether agents share a unified memory space or exchange structured summaries between steps. Assign effort levels deliberately across agents. Reserve deeper reasoning for critical decisions while keeping routine actions computationally light and cost-aware.
Prompt Engineering for Production
Claude responds predictably when prompts are structured and versioned. Store system instructions as configuration, not inline code. Inject dynamic context with clear boundaries between trusted instructions and user data. Track prompt variants against measurable outcomes. Claude’s consistency improves when templates remain disciplined and iteratively refined.
Error Handling and Resilience
Design for rate limits, refusal behavior, and reasoning escalation. Implement retries with exponential backoff and fallback routing between model tiers when latency spikes. If extended reasoning increases response time beyond thresholds, downgrade effort or switch models. Controlled degradation preserves reliability without fully interrupting user workflows.
Data Flow Architecture
Capture token categories, including input, output, cached, and thinking tokens, at every interaction. Maintain source attribution for retrieved documents used within Claude’s context window. Durable logging enables audit readiness and hallucination tracing. Context compaction strategies should summarize stale dialogue while preserving decision-critical signals. Fragmented source data weakens all of this, so teams often start with data engineering services.
Integration Patterns
Choose integration paths intentionally. Direct Anthropic API access offers granular control over reasoning and version governance. AWS Bedrock provides centralized infrastructure management and enterprise controls. When enabling Claude’s computer use capability, enforce sandboxed execution and strict tool validation to contain operational risk.
Direct Claude API vs Cloud-Managed Deployment
Each route suits different infrastructure and governance needs.
| Factor | Direct Anthropic API | Amazon Bedrock | Google Cloud Vertex AI |
| Integration | Direct API integration | AWS-managed integration | Google Cloud-managed integration |
| Identity and governance | Anthropic platform controls | AWS-native controls | Google Cloud-native controls |
| Model availability | Depends on Anthropic support | Depends on Bedrock support | Depends on Vertex AI support |
| Best suited for | Teams preferring direct provider integration | Organizations using AWS infrastructure | Organizations using Google Cloud infrastructure |
Check current model, feature, region, and pricing availability on each platform before you decide.
Enterprise Security for Claude-Powered AI Systems
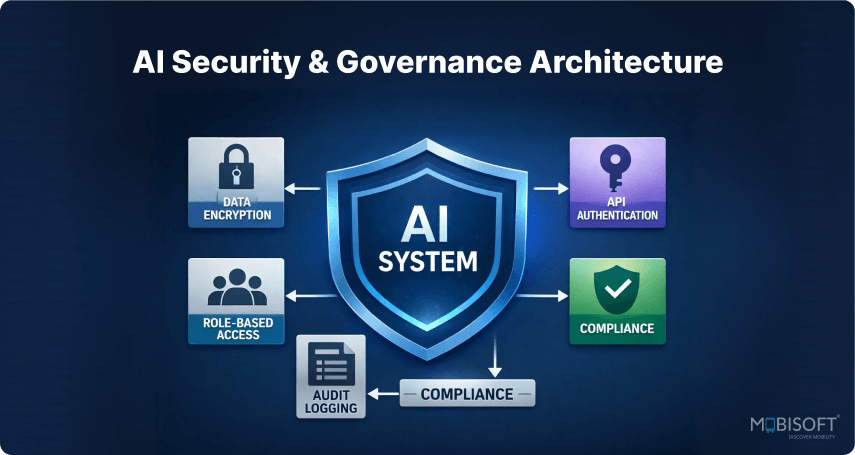
Emerging Risks in Agentic AI
- Prompt injection is a clear and present danger. It requires built-in architectural defenses now.
- Agentic workflows create new risks, like tool misuse or multi-step exploits that target process logic.
- Regulatory expectations for AI continue to evolve. AI governance should cover ongoing safety and bias monitoring, not just initial checks.
How to Protect Claude Applications From Prompt Injection
Prompt injection occurs when untrusted content attempts to influence an AI system's instructions or actions. Input filtering alone is insufficient. Production applications should separate trusted instructions from external content, restrict tool permissions, validate sensitive operations, and require human approval for high-impact actions. Prompt injection security works best as several layers.
Multi-Layered Defense Strategy
Input Layer Security
- Scrub and validate all user inputs before they touch your system prompts.
- Verify user intent and enforce strict rate limits to block automated abuse.
- Maintain strict isolation between your trusted instructions and untrusted user data.
Processing Layer Security
- Operate agents on a zero-trust principle. Give them the minimum access needed.
- Sandbox all tool execution, like code interpretation, in isolated environments.
- Validate every tool call before it runs, and watch for unusual agent behavior.
Output Layer Security
- Output filtering to prevent sensitive data leakage.
- Content safety checks before returning responses to users.
- Bias detection monitoring across different user groups.
- Use evaluation datasets, grounding checks, source attribution, and human feedback to assess output reliability. Model-generated confidence statements should not be treated as independently verified accuracy measurements.
Data Protection Measures
- Encrypt everything, and use tokenization for sensitive data before it reaches an API.
- Control access with role-based permissions, and secure your RAG knowledge sources.
- Use audit logs and access controls to support governance of your deployment.
Security Controls for Claude Applications
The table summarizes the controls above. It follows the risk categories in the OWASP Top 10 for LLM Applications.
| Security Area | Recommended Control |
| Input handling | Validate inputs and isolate untrusted content |
| Tool execution | Restrict permissions and sandbox sensitive operations |
| Data access | Apply authentication and authorization |
| Output validation | Check structured outputs and sensitive information |
| Human oversight | Require approval for high-impact actions |
| Monitoring | Log relevant security and operational events |
| Incident response | Define escalation and recovery procedures |
Audit Logs and Compliance Support
- Anthropic's Compliance API gives programmatic access to activity logs for Claude Enterprise and Claude Console organizations. Conversation and file data are available for Claude Enterprise only.
- Record model versions and prompt versions for every deployment.
- Restrict administrator access and review it regularly.
Audit logs, access controls, and deployment monitoring can support an organization's compliance processes. However, meeting HIPAA, SOC 2, GDPR, or other requirements depends on the complete system design, applicable agreements, operating procedures, and legal obligations.
Emerging Best Practices
- Consider third-party security layers for specialized threat detection.
- Regularly red-team your own AI agents to find weaknesses.
- Have a specific incident response plan for AI system failures.
Need Secure AI Architecture for Your Enterprise?
Explore development approaches that combine AI integration, governance, and operational controls.
Explore Generative AI Development
Monitoring Decision Quality in AI Systems
Claude deployments in 2026 demand LLM observability that reflects how the application behaves, not just how fast it responds. Decision quality must be measured against refusal patterns, context usage, and task outcomes. Therefore, monitoring becomes a governance layer around Claude’s behavior in live enterprise workflows.
Performance Observability
- Track latency separately for inference, tool calls, and retrieval steps within Claude-powered flows.
- Monitor effort level distribution across requests to understand when extended reasoning is triggered.
- Measure context window utilization to prevent silent token bloat affecting response time.
Reasoning and Consistency Signals
- Analyze thinking token usage to detect over-escalation of reasoning on low-risk tasks.
- Monitor refusal rates and safety-triggered responses to identify policy friction.
- Evaluate output consistency across Haiku, Sonnet, and Opus for similar prompts.
Quality Observability
- Score outputs against business KPIs, not surface fluency.
- Track hallucination incidence using source attribution logs from RAG workflows.
- Measure user acceptance and correction rates to identify drift over time.
Cost and Token Intelligence
- Break down input, output, cached, and thinking tokens per feature or agent.
- Correlate effort settings with cost spikes to refine routing policies.
- Set real-time budget alerts tied to specific Claude model tiers.
Active Runtime Controls
- Use observability data to auto-adjust effort levels when latency exceeds thresholds.
- Roll back prompt versions when refusal or inconsistency rates rise.
- Trigger model routing changes dynamically if Opus usage exceeds defined cost envelopes.
Production Claude Monitoring Checklist
| Metric | Why It Matters |
| Request latency | Measures responsiveness |
| Error and timeout rate | Identifies reliability issues |
| Task success rate | Measures workflow effectiveness |
| Evaluation score | Tracks output quality against defined criteria |
| Tool execution failures | Identifies integration problems |
| Token consumption | Tracks model usage |
| Cost per successful task | Measures operational efficiency |
| Human escalation rate | Identifies workflows requiring intervention |
Production observability should measure application behavior and task outcomes, not assume direct access to the model's internal reasoning. Evaluation datasets, source attribution, user corrections, and operational logs provide more reliable evidence of system performance.
Controlling Claude AI Costs at Scale
Model Routing Strategy
For Claude API cost optimization, a thoughtful model routing strategy is your first lever. Not every query requires the full capability of Claude Opus. Implement intelligent query classification to route simple, repetitive tasks to Claude Haiku. Reserve Sonnet for balanced needs and Opus for truly complex reasoning. This dynamic selection, based on context complexity and urgency, can lower model costs. Test each route against representative tasks, because savings depend on your workload and quality bar.
Choosing the Right Claude Model for Each Workflow
| Workload | Selection Principle |
| Classification and extraction | Start with an efficient model and validate quality |
| Standard business workflows | Balance output quality, latency, and cost |
| Complex reasoning and agentic tasks | Evaluate higher-capability models |
| High-volume production requests | Benchmark cost per successful task |
Model availability and supported settings change over time. Check Anthropic's current documentation before you commit to a model.
Token Efficiency Techniques
Direct token management is where daily savings are found. Proactively leverage features like context compaction for long conversations to keep token counts manageable. Use prompt caching for stable, repeated prompt prefixes such as system instructions, and application-level caching for reusable results. Deduplicate similar requests to avoid reprocessing identical content. These techniques shrink your context window footprint, directly lowering expenses.
Adaptive Thinking Controls
You can guide how much work Claude does to align with cost. Claude's effort parameter influences how much work the model performs when generating responses and using tools. Available effort levels and default behavior vary by model. Teams should test supported settings against representative evaluation tasks to understand their impact on quality, latency, and token usage. The max_tokens parameter provides a hard output-token ceiling. See Anthropic's effort documentation for current details.
For straightforward fact retrieval, lower effort may suffice. Reserve extended reasoning for high-stakes analysis or creative tasks. Classifying tasks upfront allows you to automatically set the appropriate effort level, balancing quality with fiscal responsibility.
Cost Optimization Techniques for Claude Applications
| Technique | Benefit |
| Model routing | Match model capability to task requirements |
| Prompt caching | Reduce repeated processing of eligible prompt content |
| Context optimization | Remove unnecessary input tokens |
| Asynchronous processing | Handle suitable non-urgent workloads efficiently |
| Budget alerts | Detect unexpected usage |
| Evaluation-driven optimization | Confirm savings do not compromise quality |
Evaluate cost optimization using cost per successful task rather than token consumption alone. A less expensive request does not necessarily create a cheaper workflow if it increases errors, retries, or human intervention. Read Anthropic's documentation on prompt caching for eligibility rules.
Enterprise Budget Controls
Finally, establish firm governance. Implement per-team or per-project quotas to democratize access while preventing budget overruns. Use real-time cost alerts and automated circuit breakers that pause services if thresholds are breached. For enterprise pricing, engage with cloud platform partners like AWS Bedrock to explore reserved capacity options versus on-demand use, aligning commitment with your actual usage patterns for optimal value.
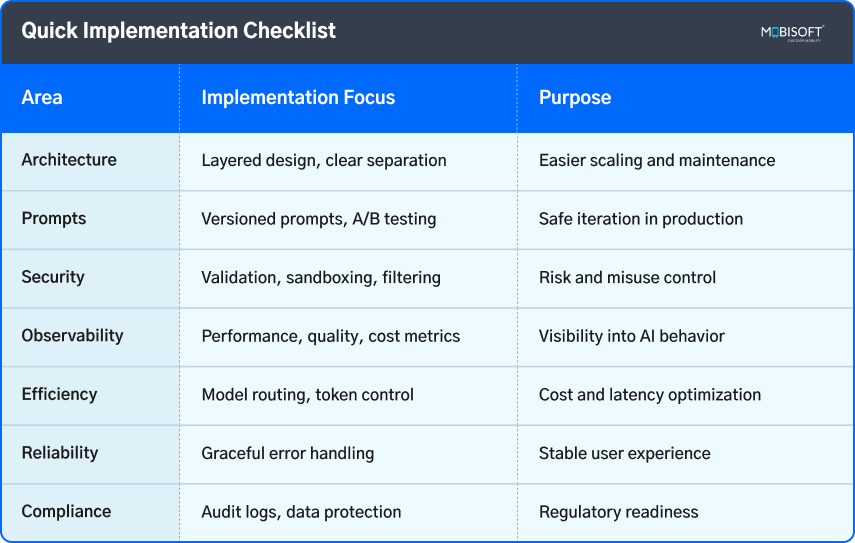
Quick Implementation Checklist
What Production-Ready AI Looks Like in 2026
Your mandate for 2026 is moving your AI applications into reliable, daily production. Remember, building trustworthy AI is not really about accessing the most advanced model. It is about constructing the resilient system that surrounds it. A production-ready AI architecture is that system.
Your checklist is clear. Implement a layered architecture and version your prompts. Build multi-layered security with sandboxed tools. Establish observability that tracks decision quality, not just uptime. Route models intelligently and control token costs. Design error handling that degrades gracefully. Ensure every output is auditable.
Begin with a single, well-scoped use case. Apply these production disciplines from the very first day. Build for reliability first, and capability second. Measure actual business outcomes, not just technical features. Iterate using insights from real production data.
The enterprises that will lead are not necessarily building the most sophisticated agents. They are building the most reliable systems. Your foundation starts now.
Planning Your Claude Production Deployment?
Discuss architecture, integrations, reliability, and operating requirements with Mobisoft's AI development team.
Frequently Asked Questions
What is Claude AI architecture?
Claude AI architecture describes the application components and operational controls used to integrate Claude into software systems. Production architecture commonly includes application logic, workflow orchestration, model access, security, monitoring, evaluation, and cost management.
How do you deploy Claude in production?
A Claude AI production deployment starts by defining the business workflow and selecting a supported Claude deployment platform. Build secure integrations, implement error handling and monitoring, evaluate outputs against representative test cases, and establish access controls and human oversight. Expand usage after the system meets predefined reliability and quality requirements.
How do you protect Claude applications from prompt injection?
Prompt injection security starts by separating trusted instructions from untrusted content. Restrict tool permissions, validate external data, and require approval for sensitive actions. Input filtering can help, but it should be combined with access controls, sandboxing, monitoring, and testing.
How can enterprises reduce Claude API costs?
Claude API cost optimization combines several steps. Enterprises can optimize prompts, use supported prompt caching, select suitable models, process eligible workloads asynchronously, and monitor token usage. Test changes against output quality and task success to avoid savings that create additional errors or rework.
Should enterprises use Amazon Bedrock or the direct Claude API?
The right Claude API architecture depends on infrastructure, governance, model availability, regional requirements, pricing, and integration preferences. Organizations using AWS may prefer Bedrock's native services, while others may choose direct Anthropic integration. Teams should compare current capabilities before deciding.
What should enterprises monitor in production AI systems?
Effective LLM observability tracks request latency, errors, task success, output quality, tool failures, token usage, cost per successful task, and human escalations. These measures help teams identify operational issues and evaluate whether the application continues to deliver business value.
Nitin Lahoti
Read more
Nitin Lahoti is the Co-Founder and Director at Mobisoft Infotech. He has 15 years of experience in Design, Business Development and Startups. His expertise is in Product Ideation, UX/UI design, Startup consulting and mentoring. He prefers business readings and loves traveling.
 Nitin Lahoti
 February 25, 2026